
Agents Inside the Regulated Core: What UK Banks Going Live With Financial-Crime and Customer-Operations Agents Reveal About Data Ownership and Hosting
The interesting question about agents in banking has moved on from whether they work. A small number of UK banks are reported to be putting them into regulated operations, and each such decision comes with two choices that determine how much risk the bank carries: who owns the data the agent reads and produces, and where the models and the agent run. Our position is that these two choices matter more than the choice of model. They are also the part of the story a mid-sized platform can learn from without copying anyone's budget, and they are architecture decisions for any team doing AI and ML development in regulated operations.
A caution first. The evidence for this commentary is a handful of headline-level press reports, several of them reporting a bank's own claims. We have not seen architecture documents, regulatory submissions or independent evaluations. What follows is analysis built on those reports, and we mark where reported fact ends and our interpretation begins.
What has been reported
Three items shape the picture.
An agent investigating financial crime inside the core. Starling Bank has been reported to have deployed an agentic financial-crime investigator inside its core, and to train a transactional model on UK sovereign cloud. The reporting also carries a time figure, 17 seconds, which is Starling's own claim. The headline-level reports we hold do not let us say exactly what that figure measures, so we do not rely on it.
An agent handling customer emails. LHV Bank has been reported to have taken an AI agent for customer emails live in the UK after a proof of concept. That is a customer-operations use case, and the path described, from proof of concept to live, is the route many teams aim to follow.
A wider pattern. The same reporting mentions a US community bank announcing a core rebuild around agents, and describes finance operations as the place where large organisations are deploying agents first. Those are medium-confidence observations. They suggest, without proving, that agents are being put to work first where operations are structured and audit already exists.
One reading of these items is that UK banks are moving agents from pilots into regulated core operations, with data ownership and sovereign hosting as design principles. We would phrase that more carefully. What the reports show is that two UK institutions have said agents are running in their operations. The "design principles" reading is an interpretation of what Starling said about hosting its model, and we have only headline-level evidence of it.
Why the core changes the question
Putting an agent in a customer-facing chatbot is one thing. Putting one inside the core is different, and the difference is the reason data and hosting dominate.
An agent inside the core reads regulated data: transactions, customer records, case histories. It may also write to that environment, by opening a case, flagging an account or drafting a response. Everything the agent sees and does becomes part of a regulated record. Three things follow.
First, the data the agent touches does not stop being the bank's responsibility because a model processes it. Second, the outputs, such as case notes, explanations and drafts, are themselves data that someone must retain, protect and be able to produce on request. Third, the agent's reasoning, if it is stored, is a new category of record that the bank will have to decide how to treat.
None of this requires a new regulation to be true. The FCA has been described in recent reporting as applying existing frameworks, such as the Consumer Duty and senior-manager accountability, to AI rather than writing agent-specific rules. If that holds, then the obligations attached to a bank's existing data and decisions attach equally to what an agent does with them. We have not examined PRA-specific expectations here, and a reader building in this area should read the primary regulatory material, not a commentary.
Choice one: who owns the data
"Data ownership" is easy to say and hard to design. In an agent deployment, it covers at least four separate things.
The data the agent reads
The first question is what the agent can see. An investigator agent may need a narrow slice of transaction and customer data; a customer-operations agent may need a different slice. Giving an agent the whole customer record because it is convenient is a design choice with consequences. A narrower view is easier to justify, easier to audit and easier to defend.
The data the agent produces
Case summaries, draft replies and recommended actions are new data created by the system. The bank needs to know where they are stored, who can read them and how long they are kept. If those outputs live with a third-party service, ownership has been decided by default.
The data used to train or tune
This is where the Starling report is most interesting. A transactional model trained on data that remains in a controlled UK environment is a different proposition from one trained where the data leaves it. We do not know the details of Starling's arrangement, and we should not guess at them. The point for a platform team is the question it raises: is the data used to train or adapt a model staying under your control, and can you say so to a regulator and to a customer?
The data about the agent
Logs of what the agent was asked, what it saw, what it concluded and what a human then did are what make oversight possible. They are also data, and they need an owner and a retention rule, set before launch rather than after the first query from a supervisor.
Choice two: where the model and the agent run
Hosting is the other half. The reporting on Starling specifically mentions UK sovereign cloud for the model. Without overreading that, it points to the range of options a platform team has to weigh.
Inside your own environment
Running the agent and the model inside the bank's own environment offers the most control over where data goes. It also puts the operating burden, including capacity, updates and security, on the bank.
In a UK-hosted environment operated by someone else
A sovereign or UK-resident cloud keeps data inside a jurisdiction while sharing the operating load. It trades some control for convenience and depends on the provider's commitments. The questions are practical: who can access the environment, under what conditions, and what happens if the arrangement ends.
In a service you call
Calling an external service is the quickest way to start. It is also the arrangement in which the questions of data location, retention and training are hardest to answer unless the terms are explicit. For regulated data it deserves the most scrutiny.
There is no single right answer, and we do not claim that any one of these is what a given bank chose. The useful discipline is to decide which of the three each part of the system will use and to be able to explain why. Different parts may rightly use different options: a model trained on sensitive transaction data may sit in a tightly controlled environment while a drafting assistant that sees only anonymised text may not need to.
Choice three: how much the agent may do
Ownership and hosting define where the data is. The third decision is how far the agent can act.
An agent that only reads and recommends is a different risk from one that changes state. The customer-emails case and the financial-crime case sit at different points on that spectrum in principle: drafting a reply for review is not the same as sending it, and surfacing a suspicious pattern is not the same as freezing an account. We do not know where either bank draws the line, and the reports do not say.
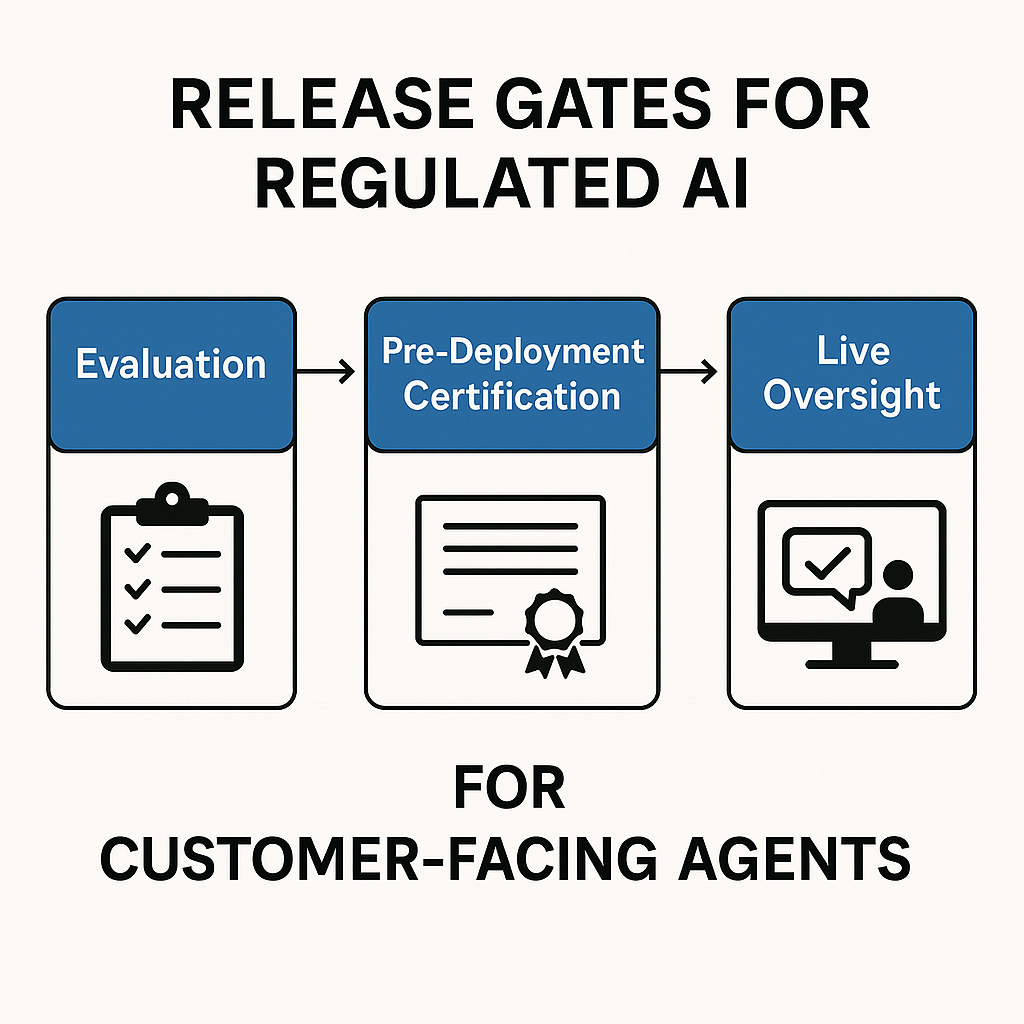
For a platform team, a staged approach is the defensible one. Start with the agent reading and recommending, with a person acting on each recommendation. Move to the agent taking low-risk actions with sampling and review. Reserve actions that affect a customer's access to money for human decision unless there is a strong, documented case. The point is not caution for its own sake. It is that each step gives you evidence about whether the agent's output is reliable enough to justify the next.
What a mid-sized platform can copy
The scale of a large digital bank is not available to most platforms, but several of the underlying choices are.
- Write the data map first. Before choosing a model, list what the agent will read, what it will produce, what will be used to train or tune and what will be logged, with an owner and a retention rule for each.
- Decide hosting per component. Classify each part of the system by the sensitivity of the data it touches and match it to an environment, rather than choosing one hosting model for everything.
- Start in a structured back-office process. The reporting suggests agents are being deployed first where operations are structured and audit already exists. That is a sensible place for a first production deployment.
- Run a proof of concept with an exit. LHV's reported path, from proof of concept to live, is a useful model, provided the proof of concept has written success criteria and a stop rule.
- Keep a human accountable. Under existing frameworks, a named person or function is still responsible for outcomes. The design should make it clear who that is for each agent action.
- Plan for dependence. If the agent relies on an external model or service, decide in advance what you would do if its terms, price or availability changed.
What we cannot tell you
We would rather be exact about the limits than let this read as a verdict.
We have no architecture detail from either bank. The Starling time figure is its own claim and we do not know how it was measured. We do not know the scope of the LHV deployment or how much human review it involves. We have no independent assessment of outcomes at either bank. And the evidence for a broader move into "the regulated core" is a small number of medium-confidence reports.
Our conclusion therefore rests on structure, not on proven results: whichever agent a bank builds, the questions of who owns the data and where the system runs will determine much of the risk. That is a claim about how to design, and it would hold whether or not these particular deployments succeed.
Where Innovify fits
Innovify is a technology partner with deep expertise in banking, financial services, fintech and insurance. We help mid to large businesses build AI-native products, modernise their technology stack and launch fintech products, and we design compliance in from day one.
For a team deciding how far to wire an agent into regulated operations, the work usually begins with the data map and the hosting decision, not the model. Our AI / ML Development work covers that kind of architecture decision, and Innovify AI Labs lets enterprise teams run several proofs of concept in parallel, test with real users and finish with a business case ready for funding. If you are weighing an in-core agent and want to test the design before committing it to production, talk to us about what a first proof of concept would look like.
FAQ
What does it mean to run an AI agent inside a bank's core?
It means the agent operates within the bank's regulated systems, reading and potentially acting on data such as transactions, customer records and cases. Because the data and the agent's outputs form part of a regulated record, decisions about data ownership, hosting and oversight carry more weight than they would for a standalone chatbot.
Which UK banks have put agents into core operations?
Reporting names Starling Bank, which is described as deploying an agentic financial-crime investigator inside its core, and LHV Bank, which is described as taking an agent for customer emails live in the UK. The reports are headline-level and the performance figures are the banks' own claims.
Why does data ownership matter for banking AI agents?
It matters because an agent reads regulated data, produces new data and generates logs, and the bank remains responsible for all of it. Ownership covers what the agent can see, what it creates, what is used to train or tune a model and what is recorded about the agent's actions.
Does an AI agent in a bank need to be hosted on UK sovereign cloud?
There is no rule we can cite that requires it. Starling has been reported to train a transactional model on UK sovereign cloud, which shows one approach. The right hosting depends on the sensitivity of the data each component touches and on regulatory and contractual obligations, which should be checked against primary sources.
Who is accountable when a bank's AI agent makes a mistake?
The bank remains accountable. The FCA has been described as applying existing frameworks, such as the Consumer Duty and senior-manager accountability, to AI rather than writing agent-specific rules. A named person or function should own each agent's outcomes.
What can a mid-sized platform copy from these deployments?
The design choices, not the scale. Map the data first, decide hosting per component, start in a structured back-office process, run a proof of concept with success criteria and keep a human accountable. These follow from the reports but have not been validated by independent evidence.
Conclusion
The first reports of UK banks running agents in regulated operations are interesting mainly for what they force a team to decide. Who owns the data an agent reads, produces and learns from, and where the model and the agent run, determine how much risk the bank carries. The evidence is thin and partly self-reported, so we treat it as a prompt for better questions and not as proof of results. A mid-sized platform can answer those questions with a data map, a per-component hosting decision, a staged scope for the agent and a named human owner.